
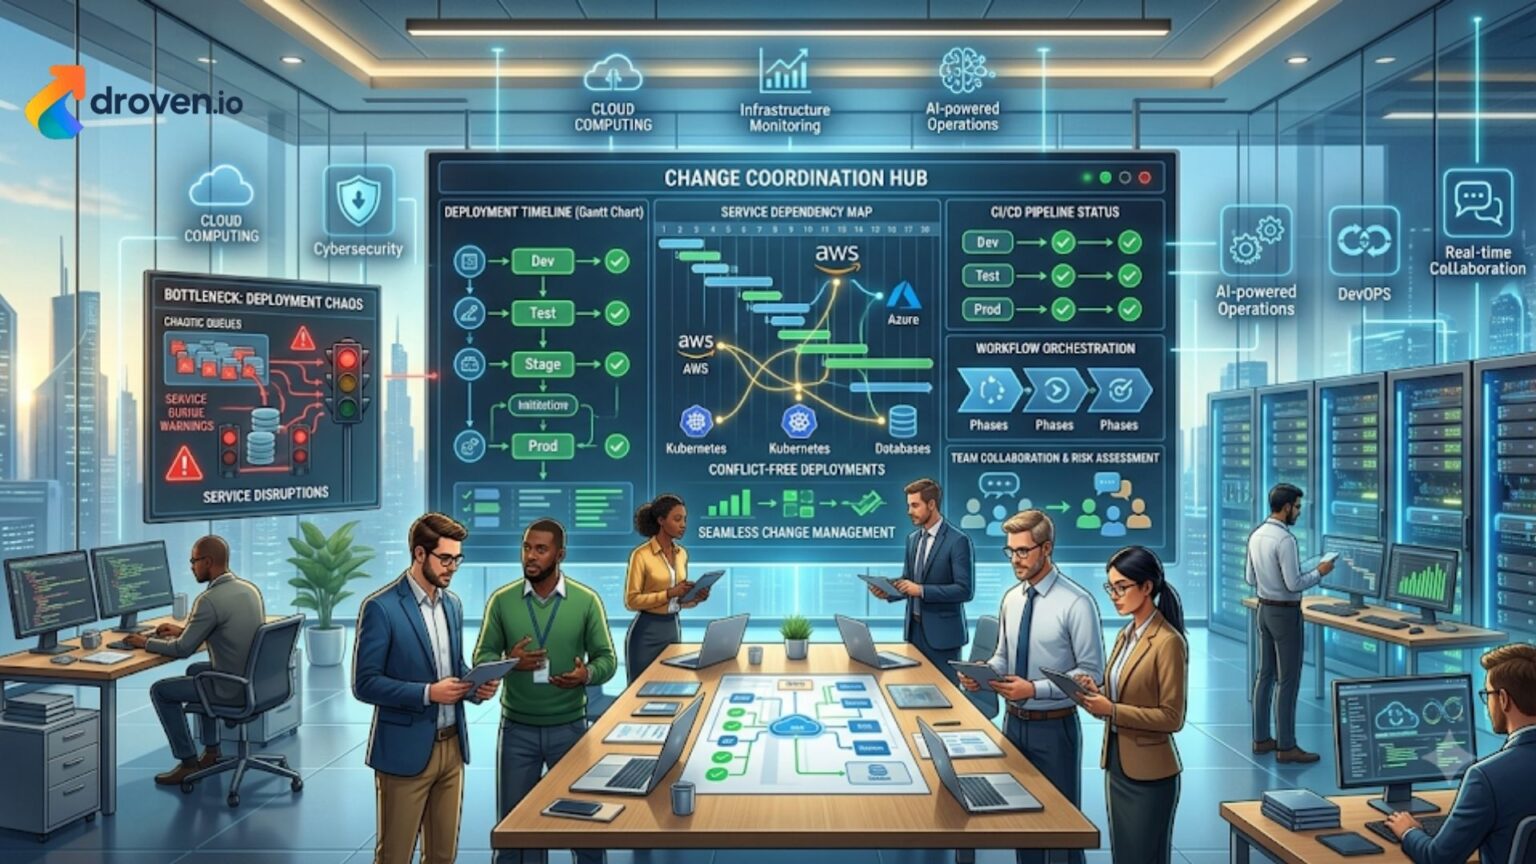
A cloud release can pass automated checks in minutes and still wait two weeks for people to agree on risk. That is the uncomfortable cloud delivery issue in 2026. The technical path is faster. The organizational path is still full of queues, handoffs, and unclear ownership.
Gartner forecast public cloud end-user spending at $723.4 billion in 2025, up from $595.7 billion in 2024. Flexera’s 2025 State of the Cloud report found that 84% of organizations named cloud spend management as a top challenge, with cloud spend expected to rise by 28%. DORA continues to measure software delivery through deployment frequency, lead time changes, failed deployment recovery time, and change failure rate. These indicators point to a practical truth: infrastructure is rarely the only constraint now. Coordination is where time, risk, and accountability collect.
This is why cloud change management needs a sharper role. It cannot mean a ticket at the end of delivery. It has to connect dependency mapping, approval logic, release timing, rollback ownership, and cross-team handoffs before production becomes the testing ground.
Why is cloud infrastructure no longer the main delay?
The old bottleneck was visible. Teams waited for servers, storage, environments, firewall changes, or database capacity. Cloud platforms reduced much of that waiting. Infrastructure as code, managed services, container platforms, serverless services, and automated pipelines gave teams faster technical access — capabilities that sit at the core of what modern cloud engineering services teams deliver and maintain.
Yet release calendars still slip.
The cloud platform can provision resources faster than the enterprise can coordinate decisions. A release waits for a database owner. A policy exception waits for security. A private endpoint waits for networking. A production slot waits for CAB. A cost approval waits for finance. These are operating model problems.
| Release dependency | Common owner | Where delay enters |
| Application code | Product and engineering | Missing test evidence or unclear rollback |
| Database schema | Data owners and DBAs | Reporting impact or migration timing |
| Identity and access | IAM and security | Privilege review or exception approval |
| Network route | Platform and network teams | Firewall, routing, and endpoint checks |
| Monitoring | SRE and operations | Missing alerts, dashboards, or runbooks |
| Cost exposure | FinOps and finance | Unclear forecast or budget owner |
Good cloud change management treats these points as part of delivery design. Weak change control discovers them late and calls the delay governance.
Cloud dependency mapping makes risk visible
Cloud estates run on hidden agreements. One service assumes an API will stay stable. One batch job assumes a storage path will retain its format. One compliance report assumes a field will mean the same thing after a release.
These dependencies rarely sit in one clean system. Architecture diagrams age. CMDB entries miss runtime behavior. Tickets describe tasks, not blast radius. Pipeline logs confirm deployment status, not business impact.
Dependency mapping gives reviewers the context they need before approval pressure begins. It should answer:
- Which services call this component?
- Which reports, jobs, or integrations depend on this data?
- Which customer journeys may degrade?
- Which controls, alerts, and runbooks need updates?
- Which teams need notice before the release window?
This is where enterprise cloud coordination becomes a delivery capability. It gives teams one view of what will change, who may be affected, who owns the risk, and what proof is required.
For larger estates, dependency mapping should use architecture records and runtime telemetry. The static view shows intended design. Runtime data shows actual usage.
Release governance should follow risk
Approval design often slows cloud delivery because it treats different changes as if they carry the same risk. Some organizations approve too much. Others approve too little and pay for it during incidents. Approval is valid. Poor routing is the defect.
| Change type | Approval path | Evidence needed |
| Standard low-risk change | Pre-approved workflow | Automated tests, policy checks, rollback step |
| Medium-risk change | Service owner plus platform review | Dependency map, peer review, observability update |
| High-risk change | CAB or risk board | Business impact, rollback rehearsal, support plan |
| Emergency change | Fast approval with review after closure | Incident link, risk note, validation result |
This makes cloud release governance more credible. A container image update with complete automated checks should not follow the same path as a database partition change during a peak processing window.
Risk-based approval also improves audit quality. Auditors need evidence that risk was understood, ownership was assigned, and the outcome was checked. A clear approval model produces better evidence than a large meeting with vague notes.
Release windows are people-readiness controls
Cloud platforms do not need release windows in the old sense. People still do.
A release window is a coordination boundary. It confirms that owners are available, support teams know what may change, monitoring is ready, and rollback decisions can happen without argument. When release windows exist only as calendar placeholders, they create false safety.
Strong cloud change management defines release windows around readiness:
- Is the service owner available during and after release?
- Is support briefed on expected user impact?
- Are monitoring thresholds updated?
- Are dependent teams aware of timing?
- Is rollback authority clear?
The purpose is to prevent the worst delay: a production issue where everyone sees the problem and nobody has clear authority to act. An internal status page complements that checklist by giving engineering, support, and dependent teams one trusted place to see what is currently degraded and what has been resolved.
This matters more in regulated sectors, shared-service models, and global delivery structures. A safe release time for one team can clash with another team’s batch cycle, trading window, claims run, or customer support load.
Cross-team handoffs need stricter rules
Handoffs are where intent gets diluted. The application team says the change is ready. The platform team says the environment is ready. Security says the exception is temporary. Operations says the runbook is incomplete. Each team may be correct inside its own boundary. The release can still carry avoidable risk.
In multi-team cloud delivery, handoffs need minimum operating rules. A good handoff note answers six questions:
- What is changing?
- What user or business impact is expected?
- What systems, data flows, or controls may be affected?
- What evidence proves readiness?
- Who can approve rollback?
- What will be checked after release?
Many failed releases would have been stopped by these six answers. Vague fields produce vague answers. Decision-grade prompts produce cleaner releases.
This is also where multi-team cloud delivery needs a named coordinator for high-risk changes. The coordinator does not own everyone’s work. The coordinator owns the release picture.
What does mature cloud change management look like?
Mature cloud change management starts earlier, uses automation where judgment is not needed, and reserves human review for risk decisions.
| Practice | What improves |
| Change intake tied to service ownership | No release enters review without a named owner |
| Dependency mapping before approval | Reviewers see impact before judging risk |
| Policy checks in CI/CD | Standard controls run before human review |
| Risk-tiered approval paths | Low-risk work moves faster |
| Release readiness checklist | Support, monitoring, rollback, and communication are checked |
| Post-change validation | Ownership continues after deployment |
| Monthly change review | Recurring friction gets removed |
This model lowers the emotional weight around governance. Delivery teams stop seeing review as a late obstacle. Reviewers stop acting as gatekeepers with partial context. Everyone sees the same risk picture earlier.
That is the practical value of cloud release governance. It gives delivery teams a shared operating model without forcing every release through the same route.
Speed improves when surprises reduce
Leaders often treat speed and control as opposing goals. Cloud delivery shows a different pattern. Poor control creates rework. Rework consumes release capacity. Incidents pull engineers away from planned work. Emergency fixes create more exceptions. The system slows because coordination failed early.
Better coordination improves speed by reducing surprises.
With mature cloud change management, teams can route standard changes through pre-approved paths, reduce late security objections, avoid release clashes across shared services, prepare support teams before impact begins, and identify rollback owners before pressure rises.
This is why enterprise cloud coordination deserves attention from engineering leaders. It is a throughput issue. It decides how much work can safely reach production.
Metrics that expose coordination health
Deployment count, incident volume, and failed changes are useful. They do not show the full coordination problem. Leaders also need metrics that expose waiting time, handoff quality, and approval friction.
| Metric | What it reveals |
| Approval wait time by change type | Whether low-risk work is slowed |
| Late dependency discoveries | Whether mapping is weak |
| Release collision count | Whether shared environments are coordinated |
| Rollback rate | Whether readiness checks work |
| Emergency change percentage | Whether planned work is becoming reactive |
| Repeat failure themes | Whether reviews lead to fixes |
These metrics should drive monthly decisions. Remove an approval that adds no safety. Add an automated check. Update a runbook. Change a release window. Clarify a service owner.
The cloud leadership question for 2026
The next improvement in enterprise cloud delivery will come less from faster provisioning and more from cleaner coordination across product, platform, security, operations, compliance, and finance.
The better leadership questions are direct:
- Who else depends on this release?
- What proof shows readiness?
- Who owns the rollback call?
- What business moment should we avoid?
- What did the last similar change teach us?
Those questions make cloud change management more than a process label. They turn it into a working system for risk, timing, and ownership.
The enterprises that move faster with fewer incidents will be the ones that remove ambiguity from handoffs, match approvals to risk, and treat coordination as part of engineering quality.
Cloud capacity is available on demand. Organizational readiness is built one decision at a time.
